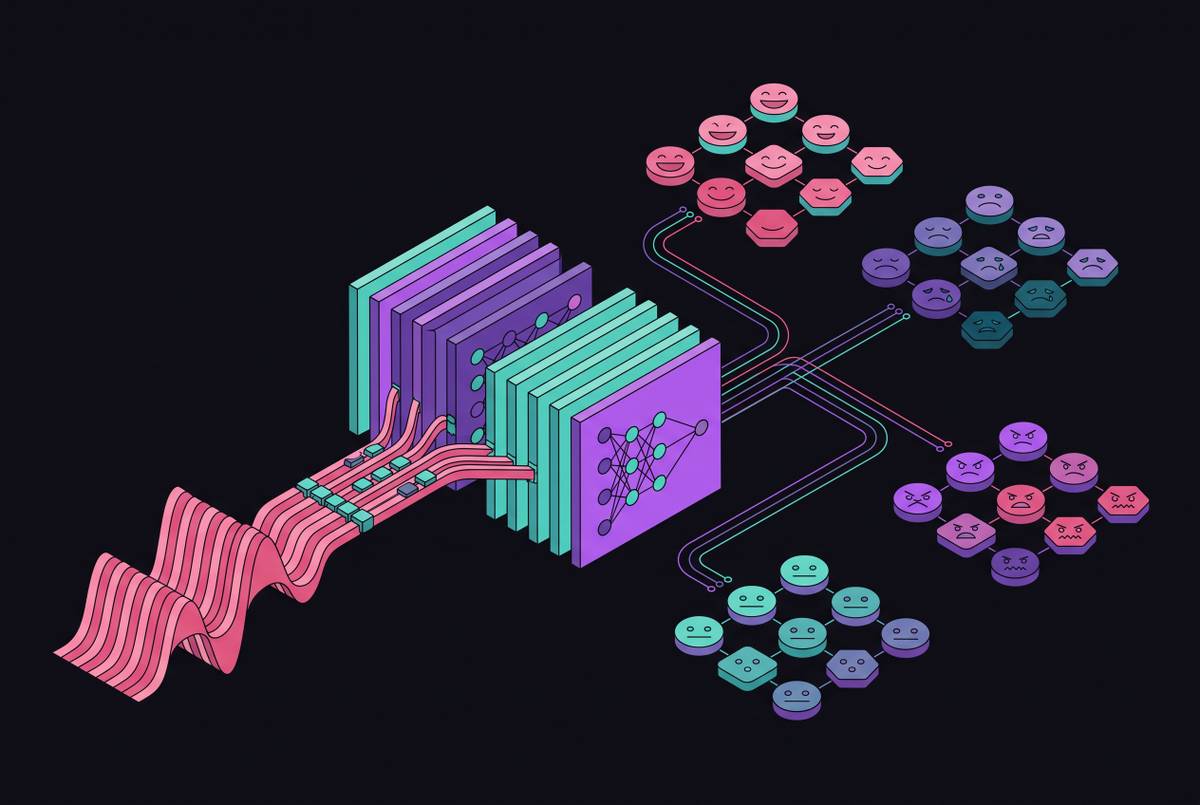
Whisper as a Speech Emotion Recognition Backbone
Whisper wasn't built for emotions, but researchers extracted real signal anyway.
Deshawn Calloway
Section
9 stories in Voice AI Research.
Whisper wasn't built for emotions, but researchers extracted real signal anyway.
Voice biometrics replaces security theater with real authentication in customer service.
Researchers reveal how attackers slip past audio deepfake detectors—and how to patch them.
Researchers finally crack synthetic speech's most annoying problem with stochastic models.
Discrete audio codes let transformers generate speech like language models generate text.
Multimodal fusion and parallel inference are reshaping production emotion recognition.
How modern speech systems extract and inject speaker identity without retraining.
Researchers compare detection methods as synthesis quality outpaces traditional verification.
Self-supervised learning cuts the transcription bottleneck for unwritten languages.