voice TTS providers for low-latency conversational AI stacks
Real latency matters more than voice quality when deploying TTS at scale.
A team building a voice agent sits down, pulls up three or four TTS demos, listens to each one read the same paragraph, and picks the voice that sounds least like a toaster reading a hostage note. Weeks later the agent is live, call volume climbs past a few dozen concurrent sessions, and the same voice that sounded warm and human in the demo starts leaving half-second gaps before every response, stepping on callers who interrupt, and losing track of what it already said. The demo told the team nothing about any of that, because the demo never had to handle concurrent load, a live telephony connection, or a caller who talks back before the agent finishes its sentence. What kills these deployments in production has little to do with how pleasant the voice sounds in isolation and everything to do with what happens once that voice gets bolted onto a real telephony stack and asked to hold up under real call volume.
Treat TTS as one component wired into a larger system when predicting production performance. Picking a provider means evaluating the latency budget it has to work within, the transport architecture carrying the audio, how the provider handles a caller talking over the agent, how its numbers behave under concurrency rather than in a single clean request, and what compliance posture it brings to a telephony environment. None of those criteria are visible in a side-by-side audio demo.
The Pipeline Budget for TTS Latency
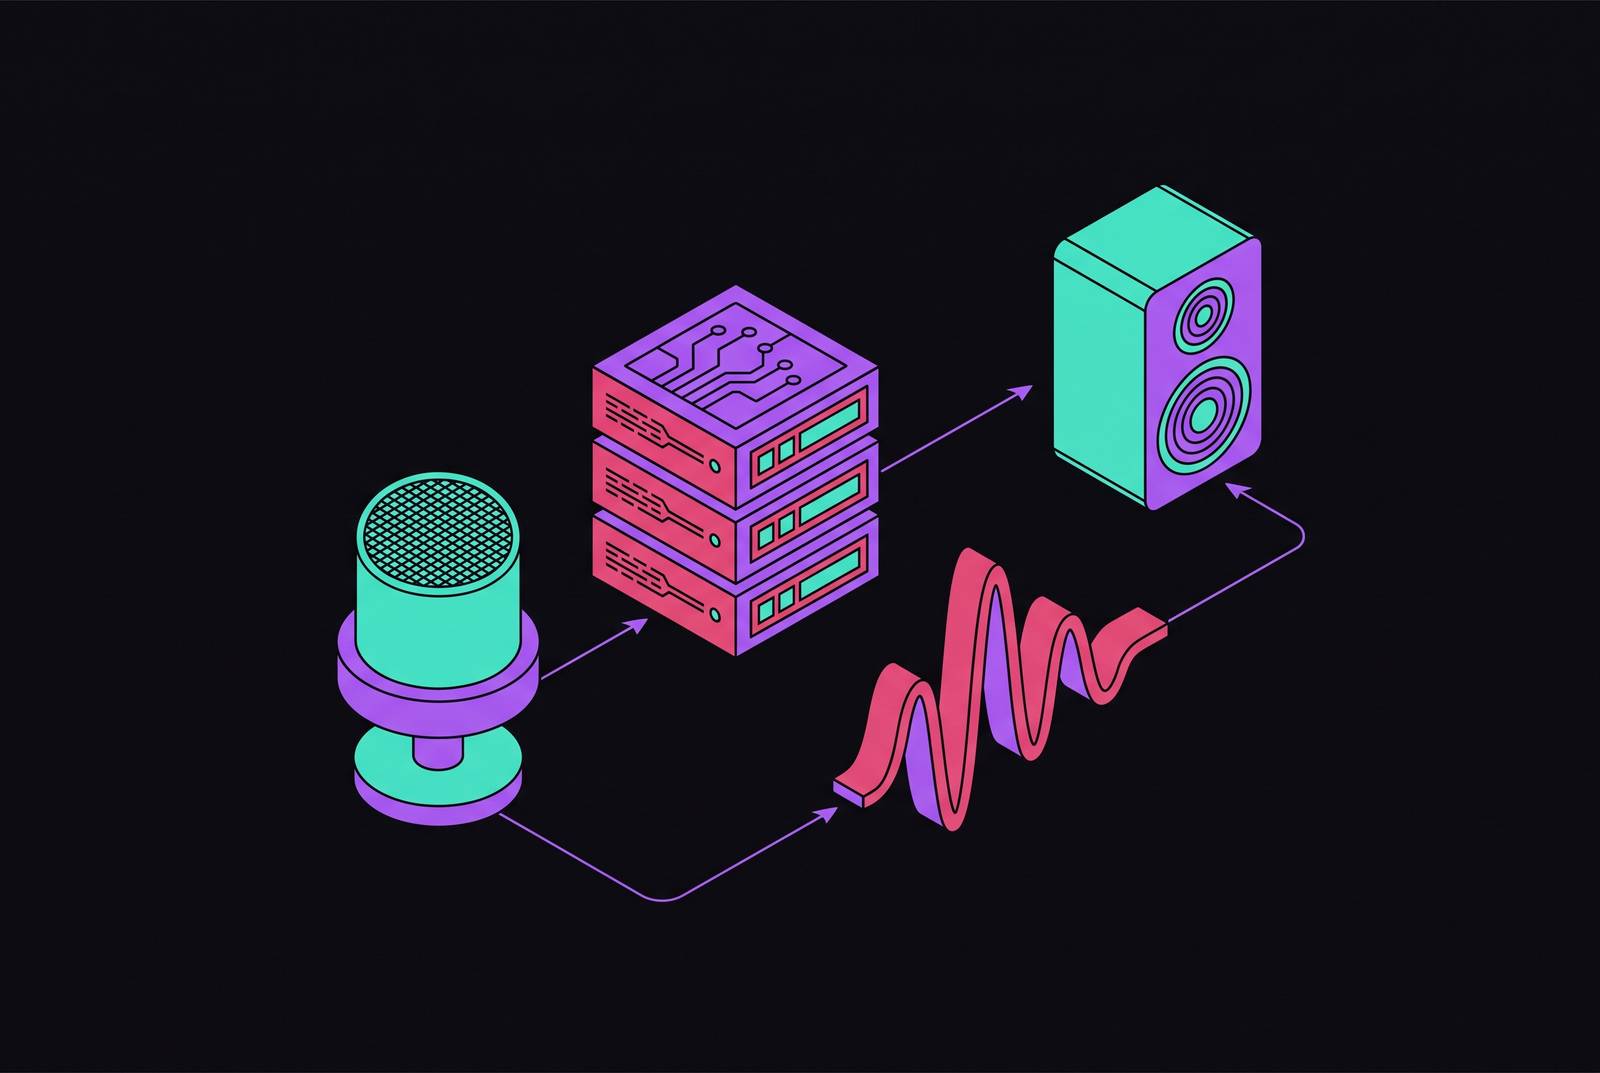
A voice agent's response to a single turn of conversation isn't produced by one system. It passes through several stages, commonly five or more depending on how a team chooses to count them, and TTS sits last among the core model stages. That position means TTS doesn't get to set its own latency budget. It gets whatever time is left once speech-to-text and the language model have already spent theirs.
The four stages and their typical ranges run as follows: speech-to-text, the LLM's first token, TTS time-to-first-audio, and network and connection overhead, which adds 20 to 100 milliseconds per turn. If you stack the low end of each range, a turn can complete quickly. But if you stack the high end, a single turn alone can blow past a full second before anyone has said a word.
Conversations that feel natural need the full round trip to land well under a second. Once STT and the LLM have taken their share, the TTS portion of that budget is already narrow, and real network conditions, jitter, packet loss, the ordinary friction of a live call, narrow it further. A TTS API that runs at the high end of its advertised range isn't a minor drag on performance. So it functions as a structural bottleneck regardless of how natural the resulting voice sounds, because by the time synthesis finishes, it has already eaten nearly the entire remaining budget before connection overhead even gets counted.
The counterargument deserves a fair hearing: if STT and the LLM are already running near the fast end of their ranges, the gap between a fast TTS response and a merely adequate one may sit below what a caller can consciously perceive, at least for a single exchange or a low-frequency use case. That holds up for a one-off interaction. It stops holding up at scale. In a high-frequency, high-concurrency deployment, every millisecond of TTS latency compounds across every turn and every simultaneous caller, and the system's ability to hold up depends not on the median response time but on the P99, the worst-case tail. An API that posts a fast median but an ugly tail will produce exactly the conversation-breaking pauses that a demo never reveals.
One more variable changes the math in a useful direction. When a streaming LLM produces its first token quickly, TTS doesn't have to wait for the full response before it starts talking. It can begin synthesizing speech as text arrives. That interleaving only works if the TTS API accepts streaming input, reading and voicing text incrementally as tokens come in, and providers vary widely in whether they support that at all.
Why published TTFA benchmarks systematically understate production latency
Vendor-published time-to-first-audio numbers are almost always lower than what independent testing finds, and the reason isn't dishonesty so much as measurement context. Vendors measure synthesis time by itself, under clean conditions, which differs from the full end-to-end performance a caller actually experiences under real concurrent load.
That gap gets produced in three specific ways. A benchmark built on single requests says nothing about what happens when the same API has to serve many calls at once, and real concurrency is exactly where latency starts spiking unpredictably, as one production evaluation confirms. Even benchmarks built by independent third parties can understate the real cost: the Coval leaderboard, for instance, strips out handshake overhead, roughly 50 to 200 milliseconds, uniformly across providers so the comparison isolates synthesis quality rather than network position. The number on the leaderboard still isn't the number a production system will actually see.
Reading any published benchmark responsibly means asking a short list of questions before trusting the headline figure: whether the number reflects P50 or P99, whether it was captured under concurrent load or a single clean request, which transport protocol was assumed, and whether the methodology predates the leaderboard change made in June 2026. A number that fails those questions isn't necessarily false, but it's incomplete in ways that matter the moment real traffic shows up.
Transport Architecture and Latency Consistency at Scale
Once a buyer has learned to distrust the headline TTFA number, the next question is what actually produces consistent latency at scale, and the answer has more to do with transport than with the model doing the synthesis. If you choose WebSocket streaming over HTTP chunk transfer, you pay connection overhead once per conversation instead of once per turn.
A WebSocket connection stays open for the life of the call. After the initial handshake, every subsequent turn in that conversation rides the same connection, so it pays no additional connection cost. HTTP, by contrast, typically opens a new connection for each request, and across a multi-turn conversation that per-turn cost adds up to real, measurable latency that a single-request benchmark will never show.
A second architectural lever appears in providers that expose it directly: the number of codebooks a model uses to represent audio. More codebooks capture finer acoustic detail at the cost of more synthesis time; fewer codebooks cut time-to-first-audio at the cost of some audio resolution. One 2026 analysis shows this trade-off concretely, comparing 8-codebook against 32-codebook configurations and finding meaningfully different TTFA and audio-to-real-time ratios between them.
Model architecture itself shapes consistency independent of the median number a vendor leads with. State Space Model architectures are built specifically to keep P99 variance low, and that tail consistency matters more for a production voice agent than a fast median, because the worst-performing interactions aren't rare anomalies at volume, they're thousands of real calls. And streaming input support, the capacity to synthesize speech as LLM tokens arrive rather than waiting for a complete response, isn't something a developer configures after the fact. A provider either built that capability into its architecture or it didn't, and without it, the LLM-to-TTS interleaving that cuts effective latency simply isn't available.
Barge-in handling as a first-class pipeline requirement, not a feature
Picture a caller halfway through confirming an account number when the agent, still reading back the previous line, keeps talking over the correction. The caller repeats the number. The agent, unaware anything was said, starts over from where it left off. That isn't a rare glitch. Barge-in, a caller speaking while the agent is still producing audio, happens constantly in any voice agent handling real call volume, and how the TTS provider handles that moment decides whether the conversation's internal state survives it.
The failure mode is specific and mechanical. If the TTS pipeline can't report back which words the caller actually heard before being cut off and which words never made it out of the speaker, the language model downstream has no reliable signal about what happened, which leads to context drift, repeated information, or conversational incoherence that compounds across turns.
Handling this correctly requires a specific protocol-level feature: an interrupt message sent over the live WebSocket connection that carries both the portion of text the caller heard and the portion that was cut short, so the conversation's state can be reconstructed accurately rather than guessed at. That capability is not uniform across providers, and an August 2026 production comparison documents real differences in how providers implement it.
That has a direct consequence for how evaluation should be ordered. Barge-in correctness belongs ahead of latency comparisons, not behind them, because a voice that sounds excellent but keeps talking over the caller, or loses track of the conversation the moment it gets interrupted, isn't a usable agent voice no matter how fast its time-to-first-audio is.
What the current provider landscape actually offers against these criteria
If you measure against pipeline fit rather than how pleasant each voice sounds in isolation, the provider landscape splits into a few distinct groups, each trading off differently against the criteria above.
Among purpose-built low-latency APIs, Gradium reports zero leading silence and holds first rank on the September 10, 2026 Coval leaderboard, the only model to hit zero on that specific metric, and it exposes the codebook trade-off directly to developers so teams can tune the balance between audio detail and TTFA per deployment. Fish Audio's S2 and S2.1 Pro models post a vendor-stated TTFA of 200 milliseconds, support more than 80 languages, and offer voice cloning from a short audio sample with cross-lingual transfer, so teams get latency and language reach at once.
Among the hyperscale cloud providers, Microsoft Azure supports high-quality TTS in many languages with both real-time synthesis and batch processing, HD neural voices with emotional tone control, and custom voice model creation, a broader feature surface than pure latency optimization.
Among integrated platform options, Bland Speech v3 is built directly into Bland.ai's own telephony infrastructure, so it isn't bolted on as a separate API call, Bland's own 2026 ranking shows. The architectural logic is straightforward: keeping TTS inside the call infrastructure removes the fragility and the compliance exposure that come from hopping out to a third-party API mid-call, and in that same source, the model ranks first among AI models on the Audio Realism Benchmark, trailing only real human speech.
Open-source options have closed much of the distance that used to separate them from commercial APIs. The gap between the best open-weight TTS models and the best commercial ones has narrowed substantially since 2023, enough that self-hosting is a legitimate option for teams with the infrastructure to run it.
xAI entered the voice API market in March–April 2026 with Grok TTS and STT, emphasizing speed, multilingual accuracy, and easy integration. Mistral AI released a TTS model aimed specifically at real-time applications. Neither has the production track record of the providers above, but both are building toward the same criteria this piece has laid out, which is the right thing to be building toward.
How Compliance Posture Filters the Candidate List
The sources checked for this guide are listed below.