C2PA Provenance Standards Applied to AI-Generated Audio
Cryptographic proof of origin replaces futile attempts to detect synthetic audio after the fact.
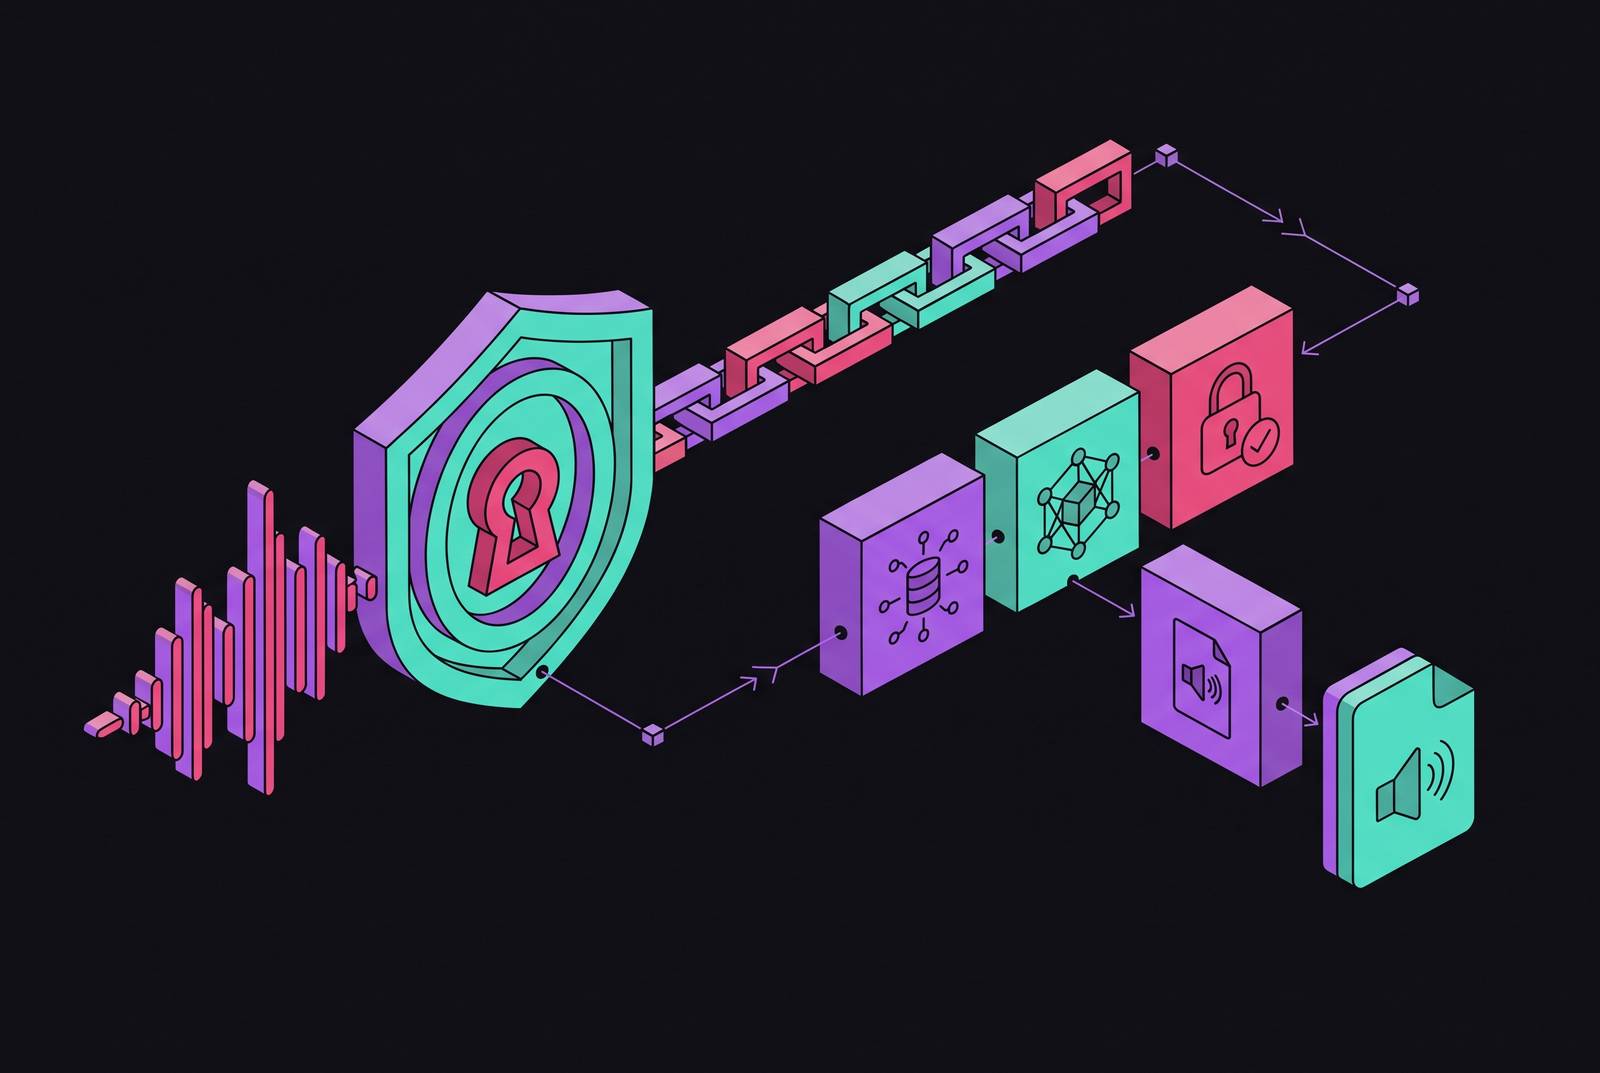
Synthetic voice has gotten good enough that asking "is this real?" after the fact is the wrong question to be asking. The Coalition for Content Provenance and Authenticity (C2PA) answers a different one: who made this, with what tool, and what happened to it since. That shift, from detection to cryptographic proof at the point of creation, is the only approach built to survive a generation-quality curve that keeps climbing. This piece lays out how C2PA works for audio specifically, where it holds up, where it doesn't, and what a compliant production pipeline actually looks like in 2026.
Why detection-only approaches are failing for AI audio
Detection assumes a tell. Something in the waveform, some statistical residue of the generation process, that a classifier or a trained ear can catch. Research on generative AI security threats found that human observers identify AI-generated images correctly only 62% of the time, and audio is a harder modality to judge by ear than a still frame. Synthetic media now routinely clears the bar of unaided human judgment, and the cost of producing it has fallen close to zero. Malicious audio can be generated at a volume no team of human reviewers could keep pace with.
Classifiers don't fare much better. A 2026 survey of deepfake generation and detection names cross-generator generalization as the field's open problem: a detector trained against one synthesis architecture frequently fails against another it hasn't seen. Every new voice model resets the clock. A classifier trained today is built to catch yesterday's fakes, and tomorrow's generator is, almost by design, the thing it wasn't trained on.
A sharper failure mode follows from the same cause: watermarking schemes meant to help detection have been shown to introduce shortcut features, patterns a detector learns to treat as proxies for "synthetic" based on superficial artifacts of the watermark itself. Content engineered to mimic or strip those features fools a watermark-aware detector. Detection-only pipelines race an improving adversary and remain vulnerable to the very provenance signals meant to help them.
What C2PA is
C2PA proves origin at the moment of creation. The coalition was founded in February 2021 by Adobe, Arm, BBC, Intel, Microsoft, and Truepic, and its core mechanism is a cryptographically signed manifest attached to a media file, usually embedded directly inside it, with a sidecar or remote manifest available for formats that don't support internal embedding.
That manifest, also called a Content Credential, is a structured record: who created the content, what tools touched it, whether AI was involved, and every meaningful edit since. Tamper with the file and the cryptographic signature breaks, making tampering visible. Inside, the assertions sit in a claim, and Public Key Infrastructure signs it. All the certificates needed to verify that signature travel inside the manifest itself, so verification needs no live call back to the original signer. A newsroom, a courtroom, or anywhere with no reliable connection can check the file cold.
That's the structural advantage over older provenance attempts. Unsigned file metadata can be edited by anyone with the right software and carries no cryptographic guarantee. Blockchain-only registration proves a hash was recorded at a timestamp, but says nothing durable about who made the content or what tools touched it along the way. A signed manifest answers both questions at once. The C2PA specification is being fast-tracked toward ISO/DIS 22144 (on hold at the Draft International Standard stage), and the first edition of JPEG Trust Part 1, Core Foundation (ISO/IEC 21617-1) published in January 2025, with a second edition in development through 2026 to align with C2PA 2.3 and add signaling for authorship, ownership, and intellectual property rights.
How C2PA applies to audio files
Audio isn't a bolted-on afterthought to a standard built for images. The specification covers formats including MP3 and WAV directly, and it extends the same manifest logic to ingredients, which are the source files used to build a composite output. A mixed track built from five stems can carry five nested manifests, one for each ingredient, so you can trace the provenance graph through the whole assembly, not just the final bounce.
The AI-specific assertions are where this gets useful for voice work. Rather than a single AI/not-AI flag, the manifest records what kind of AI involvement occurred: text-to-speech synthesis, voice cloning, AI-assisted editing, multilingual dubbing. C2PA v2.1, released in September 2024, added security and reliability improvements including a new ingredients v3 assertion, a c2pa URN namespace, time-stamp manifests, and JPEG-XL support. Buried in that list is something that matters a great deal for voice models: the ability to record which datasets informed a model's output, turning "trained on human speech" into an auditable claim.
Voice agents complicate the picture because they generate audio dynamically, not a single finished file. For those systems, the provenance question includes the consent and licensing status of whatever cloned voice the agent is speaking with. The manifest becomes the auditable ledger for that consent chain, not just a label on a static recording.
The two-layer architecture: why signed manifests need watermarking as a complement
A signed manifest is strong until someone uploads the file to a platform that re-encodes it, and most of them do. Social media and streaming services routinely recompress audio on ingestion, and that strips the embedded manifest clean off. If a perfectly signed Content Credential never survives upload, it isn't protecting much.
The industry's answer is a two-layer architecture. C2PA manifests handle the explicit, human-readable metadata layer: who made it, what tools, what edits. Imperceptible audio watermarking handles persistence: an identifier embedded in the waveform itself that survives re-encoding and points back to a manifest stored in the cloud, even after the file's internal metadata is gone. This is "soft binding," and it works by embedding a watermark carrying a UUID that resolves to a manifest store, with provisions for GDPR-compliant data residency, pseudonymity, and an offline ledger fallback for when that store isn't reachable.
The openness of the watermarking layer matters as much as its persistence. A closed, single-vendor watermarking system ties verification to one company's infrastructure. An open, freely-licensed system lets any party implement and verify the watermark independently. For a standard meant to work across newsrooms, platforms, and regulators with no shared vendor relationship, that openness is what makes cross-organization verification possible.
MerkleSpeech and chunk-level cryptographic verification for real speech workflows
File-level provenance has a blind spot: real audio gets spliced, trimmed, quoted out of context, and run through platform-level transforms that can leave some regions untouched while altering others. A signed manifest for the whole file can't tell an investigator which thirty seconds of a two-hour recording are the thirty seconds that were doctored.
MerkleSpeech, demonstrated by Tatsunori Ono of the University of Warwick in February 2026 using audio from the LibriSpeech dataset, is built for exactly that problem. It divides audio into chunks and constructs a cryptographic structure offering two tiers of assurance, public-key verifiable and localized to the chunk, achieving a 99.9% verification rate on clean, watermarked audio.
The two-tier design means that when a chunk passes watermark-only verification but fails the cryptographic integrity check, you get more than a simple failure. It's a diagnosis: the chunk has been altered since enrollment, and the system can say so, because the gap between what the watermark confirms and what the cryptographic layer confirms carries information in itself. Most current deployments can't make that claim. They produce a detector output with no third-party verifiable proof tying a specific time segment to an issuer-signed original.
That granularity maps directly onto how voice content actually circulates. A cloned voice clip excerpted into a news segment, or a customer service recording spliced together with ambient audio, doesn't raise the question "is this file real." It raises the narrower, harder question: is this particular passage authentic and unchanged since it left the model. Chunk-level verification is the first mechanism built to answer that question with cryptographic weight behind it.
Where robustness breaks down under adversarial and distribution conditions
None of this is a closed case. Both layers of the architecture, manifest and watermark, have documented failure modes the field hasn't resolved. Platforms strip metadata on upload as a matter of routine, and researchers have established that a perfectly undetectable watermark would require a degree of cryptographic secrecy that no watermark holds against a dedicated white-box adversary with access to the embedding model itself.
Distribution conditions compound the problem. Audio in the wild gets cropped, concatenated, partially quoted, resampled, and run through neural codecs, and robustness benchmarks show watermark survival degrading across certain transformation pipelines, with neural codec transcoding flagged as a particularly difficult case. A 2026 paper went further, documenting that deep audio watermarking schemes introduce shortcut features that deepfake detectors learn to rely on as proxies. Content engineered to mimic those features can deceive a watermark-trained detector. Provenance marking and detection, deployed naively together, can actively work against each other.
None of that makes provenance futile. It makes it one control among several, not the whole defense. The 2026 deepfake governance survey reaches that exact conclusion and calls for forensic detection, verifiable provenance, and institutional accountability to operate together, so no one of them carries the full weight. That's the honest frame for everything that follows: C2PA proves origin cryptographically where it survives, and the regulatory apparatus taking shape around it is the institutional leg that catches what the technology alone cannot.
The regulatory landscape making provenance compliance non-optional
Provenance stopped being optional somewhere in the last two years. A cluster of rules across the EU, the US, and China now mandate machine-readable AI content marking, which converts C2PA-compatible provenance from an industry best practice into a legal requirement in the jurisdictions that matter most for audio distribution.
California SB 942 takes effect August 2, 2026, and it requires large AI providers to disclose AI involvement in generated content. California AB 853, effective January 2027, goes further on the distribution side: platforms must detect and surface provenance data on content they carry, and the law prohibits stripping provenance data from anything uploaded or distributed through them. China's AI content labeling regulations have been in force since September 2025, and they make both visible and machine-readable marking mandatory for AI-generated content, covering audio alongside other media.
The standard is also moving past commercial media. The Library of Congress has led the C2PA for G+LAM group since January 2025, and it brings cultural heritage organizations and government bodies together to work through C2PA implementation across archives, libraries, and museums. That's provenance becoming public-record infrastructure, not just a platform compliance checkbox.
For any platform generating AI audio at scale, TTS narration, multilingual dubbing, voice agent output, the practical conclusion is the same across every one of these rules: provenance has to be embedded at creation time. Retrofitting it onto a production pipeline after the fact is structurally harder than building it into the generation step from the start, and under AB 853's anti-stripping provision, waiting isn't a compliance strategy so much as a liability.
Where AI audio production is most exposed
The sectors moving fastest on AI audio adoption are the ones that carry the sharpest exposure under this regulatory environment. Speed of deployment and depth of obligation are rising together, not separately.
Podcasting is the clearest case. A growing share of new shows launched in 2026 use some combination of AI voice generation, AI-assisted scripting, or AI multilingual dubbing, and top US shows using AI dubbing have seen measurable growth in cross-border listenership as a result. Every one of those pipelines, the ones driving the growth, is now also the one that has to carry a provenance chain end to end.
Advertising has picked up a chain-of-title audit requirement: a documented C2PA trail for every AI-generated audio asset in a campaign is now part of pre-buy compliance, and agency master service agreement risk allocation guidance has turned AI-specific indemnity into an active negotiation point in both client and vendor contracts. That's a legal department problem as much as a production one.
Enterprise voice agents carry the most distinctive obligation of the group. If an agent speaks in a voice cloned from a real person, the provenance and license behind that voice have to be auditable, and if the person withdraws consent, the organization needs a documented revocation trail showing the clone stopped being used. GDPR Article 9 applies wherever biometric voice data is processed, which puts voice cloning in the same regulatory category as fingerprint or facial recognition data, not a lesser one.
Litigation has already pushed the music side of the industry toward formalized rights chains. The UMG-Udio settlement on October 29, 2025, and the WMG-Suno settlement on November 25, 2025, moved both platforms toward licensed, opt-in models through 2026, a signal that provenance documentation is becoming an expected part of licensing compliance well beyond what any single law requires.
Building a C2PA-compliant AI audio pipeline in practice
Provenance has to be a property of the generation step, not a label applied afterward. That means the TTS or voice-cloning model itself needs to emit a signed C2PA manifest at the moment it produces output, capturing model identity, input sources, and any AI-specific assertion (synthesis, cloning, dubbing, AI-assisted edit) as part of the generation call, not a separate metadata pass bolted on before publishing.
Every ingredient in a composite asset needs its own manifest carried through the build. A narrated audiobook chapter assembled from a TTS pass, a human-recorded intro, and a licensed music bed should resolve, on inspection, into three traceable components, each with its own signed origin, not one flattened file-level claim.
Because metadata strips on upload, the watermarking layer isn't optional alongside the manifest. Pipelines need an embedded, imperceptible watermark carrying a persistent identifier that resolves to a cloud manifest store, with an offline ledger fallback for when that store is unreachable, matching the soft-binding approach the standard already specifies.
For any workflow where audio gets spliced, excerpted, or partially reused, segment-level verification can confirm which specific passage is authentic even when the rest of the file has been altered. Chunk-based cryptographic structures, in the spirit of what MerkleSpeech demonstrated, give teams the ability to answer "which part of this recording is authentic" rather than only "is this file, as a whole, authentic."
Voice agent deployments need a consent and revocation ledger as a first-class system, not an afterthought bolted onto a compliance review. If a cloned voice's rights holder withdraws consent, you need a documented trail showing exactly when the clone stopped being used in production, because GDPR Article 9 treats that voice data as biometric data, and those obligations don't bend for convenience.
Finally, every one of these pieces needs to exist before a regulatory deadline forces the issue, not after. SB 942 is already in effect. AB 853 arrives in January 2027. Building provenance into the generation step now is the only version of compliance that doesn't involve reconstructing a production pipeline's history after the fact, which is close to impossible to do credibly once the audio is already out in the world.
Sources
- Deepfakes and Synthetic Media: Generation, Detection, and Governance
- From AI-Generated Content to Agentic Action: Security and Safety Threats in Generative AI
- Authenticated Contradictions from Desynchronized Provenance and Watermarking
- MerkleSpeech: Public-Key Verifiable, Chunk-Localised Speech Provenance via Perceptual Fingerprints and Merkle Commitments
- New Community of Practice for Exploring Content Provenance and Authenticity in the Age of AI