Speaker Diarization in Multi-Party Meeting Transcription
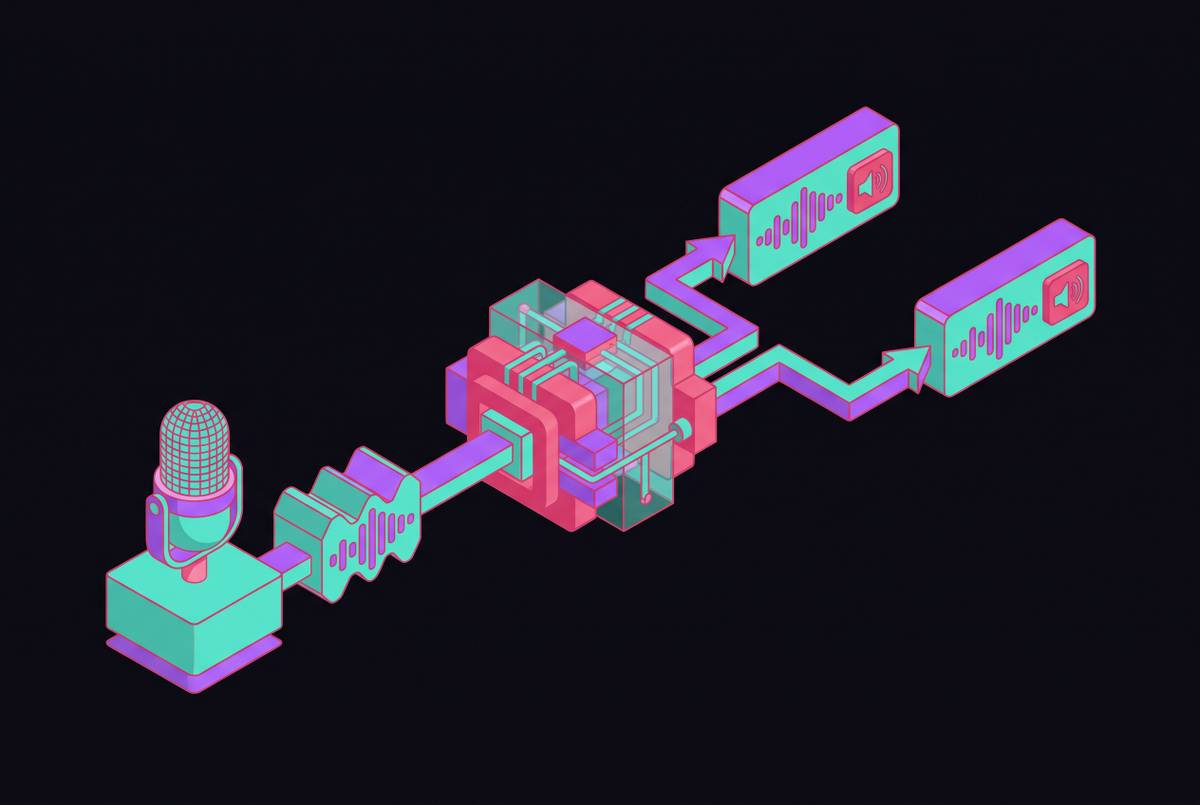
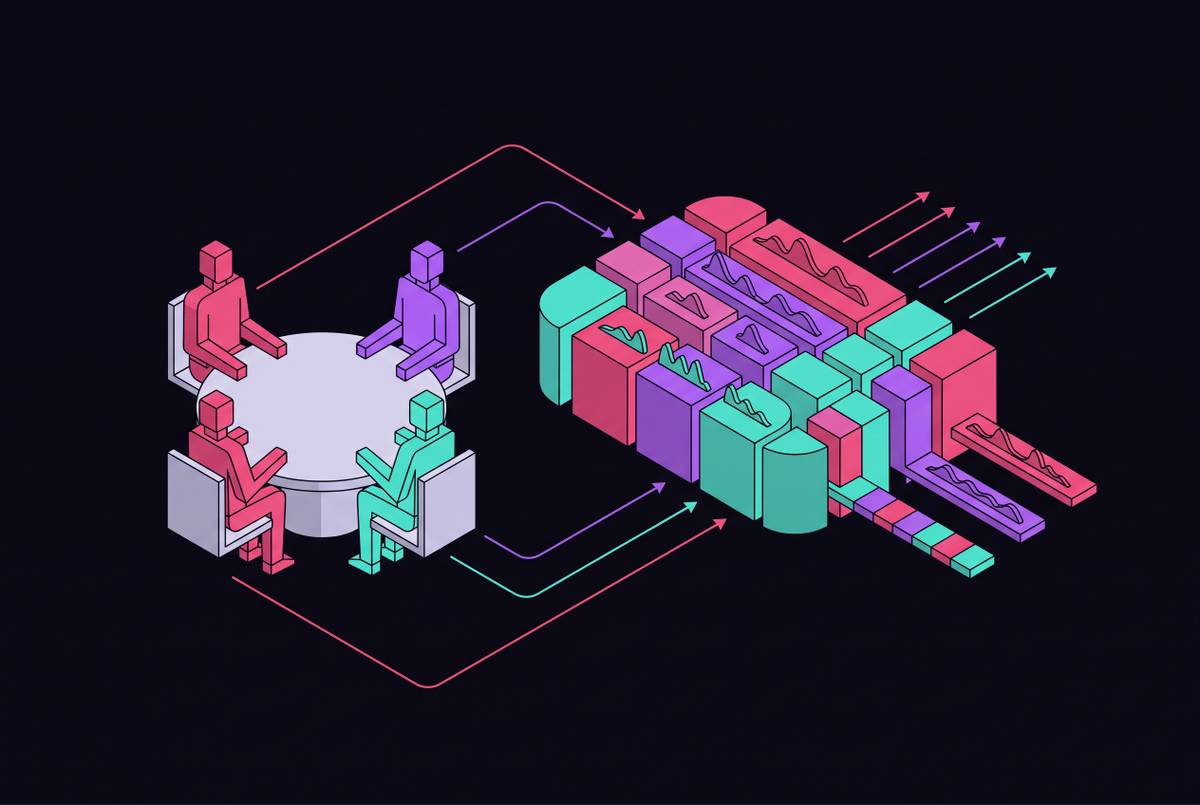
Clustering-based systems still can't match ASR accuracy on real meeting audio.
Priya Subramaniam
Clustering-based systems still can't match ASR accuracy on real meeting audio.
Transcription errors compound across multilingual centers, breaking every analysis built on top.
Popular STT accuracy scores hide massive performance gaps across accents and dialects.
Latency at every stage compounds into delays that break the illusion of natural conversation.
Copyright law leaves voice actors defenseless against AI clones of their own voices.
AI can now clone any voice from just seconds of audio.
Hidden fees and pricing models can multiply TTS costs four times over at scale.
Different conditions require different TTS approaches—one solution doesn't work for both.
Markup handles pronunciation and pacing; neural models handle everything else.
AI voices now handle audiobook backlogs that human narrators alone cannot scale to meet.
Quality and brand voice consistency matter more than language count when scaling globally.
Choose your platform based on whether you can own the integration failures yourself.